SEO Log File Analysis: Find Crawl Waste and Protect Your Crawl Budget
Learn how server log files reveal which URLs search engine crawlers visit, skip, or revisit too often. Use a practical analysis process to spot crawl waste and prioritize fixes.
When important pages take too long to appear in search, start by checking whether search crawlers actually request them. Server logs can show that a crawler repeatedly visits filter combinations, follows outdated redirects, or encounters errors while newly published pages receive little attention. This walkthrough explains how to build that evidence, separate genuine search bots from other traffic, and prioritize fixes without treating every repeated crawl as waste.
Crawling and indexing are different stages. A logged request proves that your infrastructure handled a request; it does not prove that a search engine rendered the page, accepted its canonical, or indexed it. Use logs alongside crawl reports, URL inspection, sitemap data, and your own technical crawl.
What Server Logs Reveal About Search Crawlers
Access logs record requests to a server or delivery layer. Depending on the logging configuration, each record can contain a timestamp, client IP address, request method, hostname, URL path, query string, response status, user agent, bytes transferred, and processing time. These fields let you reconstruct which URLs a crawler requested, how frequently it returned, and what your infrastructure sent back.
For a large website, the most useful view is rarely a list of individual requests. Group activity by page type and purpose: products, categories, editorial pages, internal search results, filters, pagination, assets, and retired URLs. This reveals whether crawler attention broadly matches your intended search inventory. A busy bot is not necessarily reaching the pages that matter.
Discovery: Did the crawler request a newly published URL, and how long after publication did the first observed request occur?
Coverage: Which eligible URLs received requests during the observation window, and which did not?
Recrawl behavior: Are frequently updated pages revisited, or does most activity concentrate on stable, low-value URLs?
Delivery problems: Which requests returned redirects, client errors, server errors, or unusually slow responses?
URL expansion: Are query parameters or path patterns creating large numbers of alternate URLs?
Infrastructure differences: Do crawler requests behave differently by hostname, delivery layer, or deployment period?
Crawl budget is not a fixed allowance you can read from a log. Search engines balance their willingness to crawl a site with the site's ability to serve requests reliably. Logs show the resulting activity, not the crawler's internal allocation. Before diagnosing a budget problem, rule out simpler causes of slow discovery: weak internal links, missing sitemap entries, robots restrictions, incorrect canonicals, and pages that are not accessible through normal navigation.
Collecting and Preparing Log Data
Locate the layer that sees the crawler
Ask your infrastructure team where public requests are recorded: a content delivery network, reverse proxy, load balancer, or origin web server. If a CDN serves a cached page without contacting the origin, the origin log alone will miss that request. Edge logs are usually the better starting point for public crawl activity, while origin logs help explain backend failures and processing delays.
Check whether exports are complete or sampled, which hostnames they include, and how long records are retained. Collect all relevant public hosts, including separate mobile, international, or asset hosts when they affect the investigation. When combining layers, keep their records distinguishable: one external request may produce several internal records, so adding them together can inflate crawl counts.
Request timestamp with a documented timezone, preferably standardized to UTC.
Requested hostname, path, and query string; retain the raw URL alongside any normalized version.
Request method and response status code.
User-agent string and the original client IP, obtained through a trusted infrastructure configuration.
Response duration with a clear definition of what that duration measures.
Optional diagnostic fields such as cache status, response bytes, edge location, and upstream status.
Treat forwarded client-IP headers cautiously. A proxy may record its own address unless configured to preserve the original client IP, while untrusted incoming headers can be forged. Have the infrastructure team confirm which field represents the external client and how trusted proxies handle it. This matters both for bot verification and for avoiding misleading traffic attribution.
Build a clean, comparable dataset
Choose an observation window that includes ordinary traffic and enough time for your site's typical recrawl behavior. Several weeks can be a practical starting point, but slowly crawled sections may require a longer window. Record migrations, releases, outages, and major publishing changes so that a temporary event does not become your baseline. Save the raw export before applying transformations.
Parse records into a consistent schema, remove duplicate exported records where you can identify them reliably, and flag malformed entries. Do not deduplicate legitimate repeat requests. Preserve URL case and meaningful query parameters; merging them prematurely can hide the exact variants causing waste. For analysis, create separate fields for raw URL, page type, parameter keys, and a comparison key that follows your site's actual URL rules.
Join the logs to a URL inventory from your CMS, product database, sitemaps, and technical crawler. Include publication date, page type, intended indexability, canonical target, sitemap membership, and internal-link information where available. Keep observation dates for these attributes: a page's current robots directive or status may differ from what the search crawler received earlier.
Logs may contain IP addresses, authentication-related values, or personal information in query strings. Restrict access, redact sensitive fields before sharing, and follow your organization's retention and privacy requirements. Avoid distributing full raw logs when an aggregated report answers the question.
Separating Search Bots from Other Traffic
A user agent containing Googlebot or Bingbot is a candidate, not proof of identity. Anyone can send that string. Start with user-agent filtering, then verify candidates using the search provider's documented method. Depending on the provider and crawler type, that may involve published IP ranges or reverse DNS followed by forward DNS confirmation.
For DNS-based verification, look up the requesting IP's hostname, check that it matches the provider's documented domain rules, then resolve that hostname back to confirm the original IP is included. A name that merely contains a provider's brand is insufficient. Cache verification results to avoid repeating expensive lookups, but refresh them appropriately and retain unresolved requests in an uncertain category.
Verified search crawlers: requests that pass the relevant provider's verification procedure.
Unverified claimed search crawlers: matching user agents without adequate verification.
Other automated traffic: monitoring tools, SEO crawlers, scrapers, and bots serving other purposes.
Human or unknown traffic: requests that do not fit a confirmed automated category.
Within verified traffic, separate ordinary search crawling from advertising, image, video, inspection, and other specialized fetchers where identifiable. A user-triggered inspection request should not be counted as evidence that normal discovery improved. Likewise, keep HTML document requests separate from CSS, JavaScript, images, and other resources; rendering-related resource requests are not automatically waste.
Document the classification rules and verification coverage in your report. If client IPs are unavailable, you can still analyze claimed bot traffic, but describe that limitation explicitly. Do not combine verified and unverified requests into a precise claim about how a search engine crawls your site.
Spotting Crawl Waste and Missed Pages
Create a baseline before inspecting individual URLs
Summarize verified search requests by day, crawler type, hostname, page family, and status class. For each important page family, calculate total document requests, distinct requested URLs, requests per URL, and the proportion of your intended indexable inventory requested during the window. This separates two different problems: excessive repetition on a small set of URLs and expansion into a large set of unwanted variants.
For recently published pages, compare publication timestamps with the first verified document request. Call this first observed crawl delay, not absolute discovery time: the crawler may have known about the URL earlier, and your records may not cover its entire history. Pages with no request by the end of the window belong in an unobserved group, not in an invented average delay.
Investigate URL families that consume attention
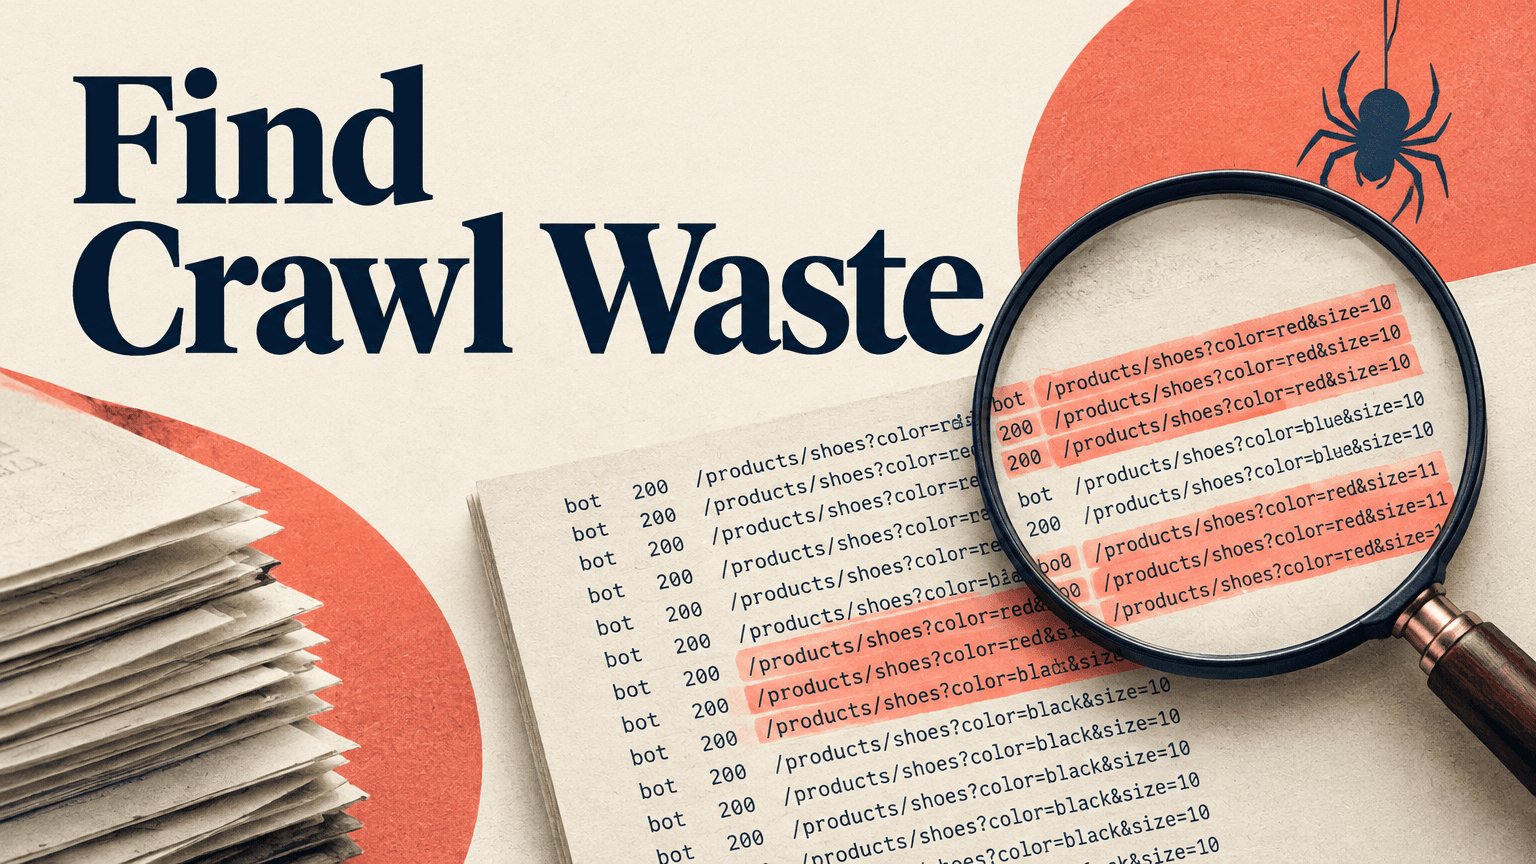
Faceted navigation: combinations of size, color, availability, or sort order that generate many near-duplicate pages.
Internal search: crawlable result URLs whose terms or pagination create an open-ended space.
Session and tracking variants: parameters that change the URL without materially changing the document.
Redirecting URLs: outdated links that make crawlers request an old address before reaching the destination.
Broken or retired URLs: repeated requests returning 404 or 410, especially when current templates still link to them.
Error-prone pages: URL families with recurring 5xx responses, timeouts, or delivery-layer failures.
Duplicate paths and hosts: alternate URL forms that remain accessible despite a preferred version.
For each family, inspect representative URLs, their response content, canonical declarations, robots directives, and internal entry points. A high request count alone is not a waste diagnosis. Pagination can expose valuable products; selected filters can satisfy distinct search demand; repeated crawling can be appropriate for changing inventory. Label a family inefficient only after comparing its activity with its intended role.
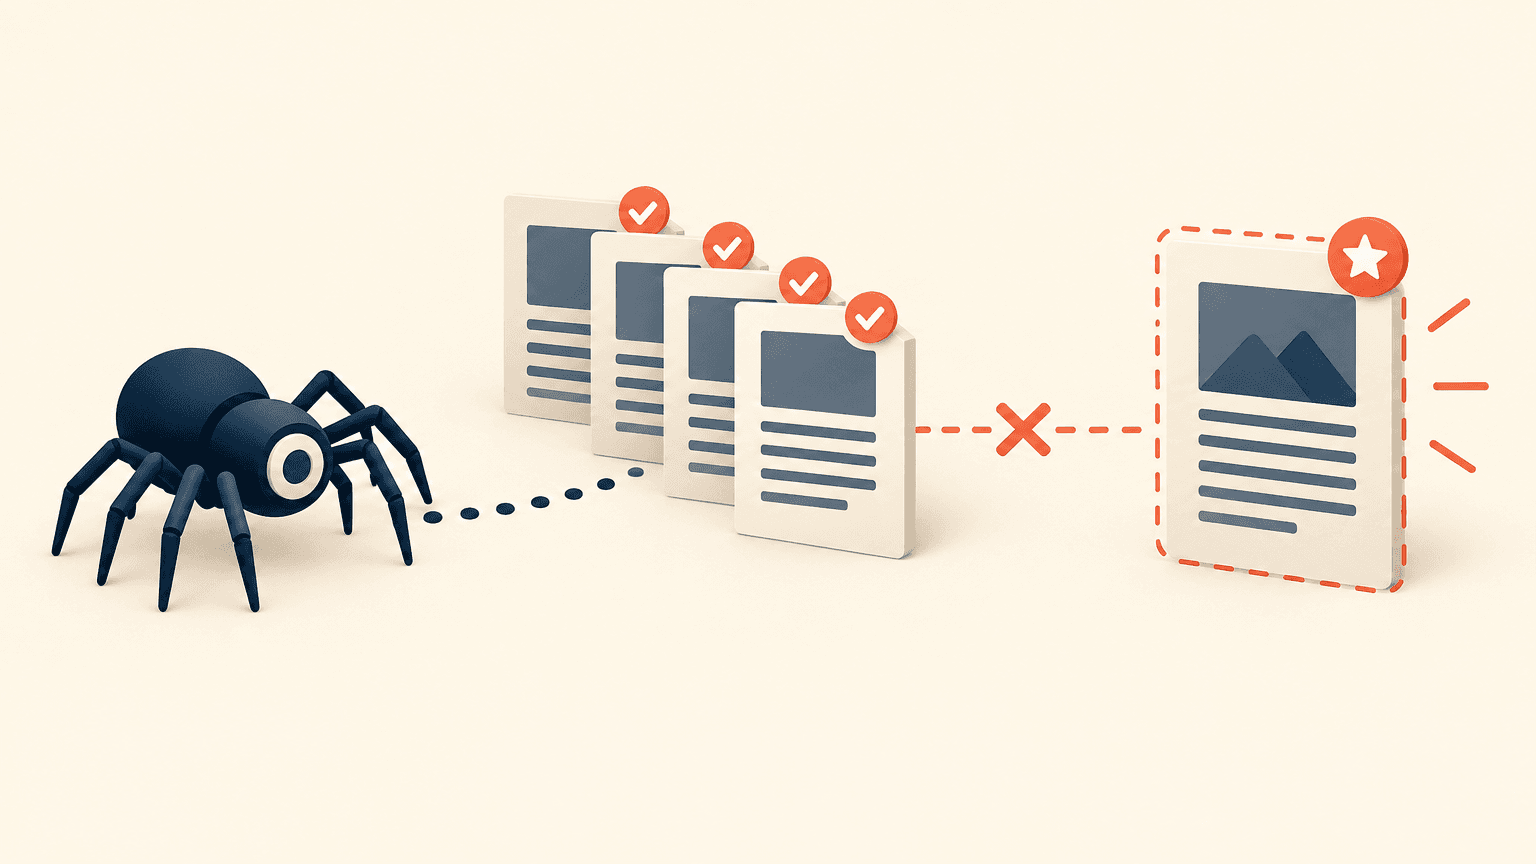
Hypothetical example: a catalog site receives many verified document requests for URLs containing both sort and availability parameters, while new product pages are rarely requested. If those parameter combinations reproduce the same inventory and are linked throughout category templates, the evidence supports investigating that URL expansion. It does not prove that blocking the combinations will cause immediate indexing of the products.
Find valuable pages with no observed crawl
Compare your eligible URL inventory against verified document requests using a left join or equivalent lookup. Prioritize unrequested URLs by business importance, publication age, and page type. Check whether they have crawlable internal links, appear in a relevant sitemap, return a usable response, and declare consistent canonical and indexability signals. An orphan page needs a discovery fix, not merely a reduction in requests elsewhere.
Logs do not normally reveal the full route a search crawler followed. Referrer data may be missing, and adjacent requests are not reliable proof of a navigation sequence. Reconstruct inefficient paths by combining requested URL patterns with a technical crawl's link graph. Use that graph to identify the template or navigation element exposing unwanted URLs and to check whether valuable pages sit behind unnecessary hops.
Review response times by URL family and status, including slower-tail behavior rather than only an overall average. Confirm whether your timing field measures origin work, edge processing, or the full response. An edge request that returns 200 can conceal a slow upstream dependency, while a quick 200 can still serve an empty page or soft error. Investigate response content and search-engine reports before declaring delivery healthy.
Turning Log Findings into Technical SEO Fixes
Turn each finding into a specific issue with evidence, affected URL patterns, likely entry points, a proposed change, an owner, and a validation plan. Prioritize by the importance of affected pages, the scale of avoidable requests, the severity of the failure, and confidence in the diagnosis. Broad availability problems generally deserve attention before fine-tuning crawl distribution.
Repeated 5xx responses or timeouts: investigate capacity, application failures, caching, and crawler-facing security rules. Verify that fixes work at the public delivery layer.
Important pages with no observed requests: add relevant crawlable internal links, remove accidental restrictions, and include preferred indexable URLs in appropriate sitemaps.
Internal links to redirects: update links to final destinations and shorten chains while preserving redirects needed for users and old external links.
Unwanted parameter combinations: reduce their generation and internal exposure, then select canonicalization, crawl controls, or other handling according to their actual purpose.
Duplicate URL forms: align internal links, sitemaps, canonicals, and redirects around the preferred versions.
Retired URLs still linked internally: remove or replace obsolete links; redirect only when a genuinely suitable replacement exists.
Choose crawl controls without blocking needed signals
Canonical tags identify a preferred version of duplicate or similar content, but they are not a guaranteed crawl-prevention mechanism. A noindex directive requires a crawler to access the page to see it, so it is not a direct solution to excessive fetching. Robots.txt can restrict crawling, but it does not reliably remove a known URL from search results and can prevent a crawler from seeing a page-level noindex or canonical.
Do not block a URL family in robots.txt simply because you want its noindex or canonical processed. Define the desired outcome first: prevent discovery, reduce crawling, consolidate duplicates, or remove pages from indexing. These goals require different tools and sometimes a staged rollout.
For facets, decide which combinations deserve indexable landing pages and which exist only to help users refine results. Keep valuable combinations accessible through clear links and stable URLs. Reduce crawlable exposure of unwanted combinations without breaking navigation or hiding required rendering resources. Test pattern-based rules against legitimate URLs before deployment; a broad parameter or directory rule can accidentally cover important pages.
Use sitemaps to present preferred, eligible URLs rather than every URL your application can generate. Supply accurate last-modified values for meaningful page changes, not automatic refreshes on every export. Sitemaps help discovery but do not replace internal links or guarantee crawling and indexing. Similarly, returning 404 or 410 for genuinely removed pages is normal maintenance, not a problem to conceal with irrelevant redirects.
Validate the change against the original problem
Record deployment dates and compare equivalent periods, accounting for publishing volume, inventory changes, outages, and crawler variability. Measure whether unwanted URL families receive fewer requests, errors decline, and important page cohorts gain observed crawl coverage or shorter first observed crawl delays. Keep bot verification, URL grouping, and log completeness consistent so that a reporting change does not masquerade as an improvement.
Then check the separate indexing outcome through search-engine reporting and representative URL inspections. More crawling does not guarantee indexing; if a page is fetched successfully but remains excluded, investigate content value, duplication, rendering, and canonical selection. Nor should you expect requests removed from one area to transfer one-for-one to another. The useful result is better access to your intended search inventory, not a particular total request count.
Start with one valuable page cohort and one suspected source of crawl waste. Collect complete delivery-layer logs, verify the search bots, join requests to your URL inventory, and trace the relevant internal links. Use that evidence to ship a bounded fix with a clear validation metric before expanding the investigation across the rest of the site.